GPT-5.5 and GPT-6 Astra tackled the same WordPress feature with minimal and detailed prompts. Smaller patches took longer, and the code told a richer story than the scores.
OpenAI’s recent recommendation for GPT-6 Astra is to revisit the instructions surrounding our coding agents. Some guidance written for earlier models may now hinder useful judgment. Its article, Rethinking skills and prompts for GPT-6 Astra, prompted me to test that proposition on my own website.
The old habits had reasons. A model skipped tests, so we added a rule. It changed unrelated files, so we tightened its scope. It stopped early, so we defined completion. Eventually, our prompts became operating manuals.
Our prompt stack can become a fossil record of previous model failures. The question is which instructions still prevent failures today.
What OpenAI proposes
OpenAI recommends concise skills, progressive disclosure and documentation relevant to the task. Loading everything consumes context; rigid recipes can overconstrain a capable agent. It also says Astra checks its work more readily, so inherited testing reminders can produce unnecessary work.
Its advice retains boundaries and explicit completion criteria. Astra can be tentative about continuing, making clear authorization and stopping conditions useful. That is vendor guidance to investigate, rather than a result this experiment proves. Read the original guidance.
One feature, four isolated runs
I tested how prompt specificity affected behavior, speed, scope, validation and implementation style. The feature was a responsive live market clock for Beast’s Almanack: Tokyo, London and New York, country flags, AM/PM time, correct daylight-saving handling and styling consistent with the existing WordPress site.
A reviewed implementation could eventually serve the real site. A plausible clock at one instant, however, cannot establish year-round correctness or successful mobile integration.
| Control | Recorded setup |
|---|---|
| Design | Two models × two prompt styles; one run per condition |
| Starting point | Same theme commit in isolated repository copies |
| Baseline | a0f918e84b2f5bef1564f90ed0a73598f0bcfbf4 |
| Agent | Codex CLI 0.154.0; medium reasoning |
| Tools | Node 24.11.0; Python 3.14.0; Git 2.47.1.windows.2 |
| Permissions | Workspace-write; approvals never |
| Evaluation | Same harness and validators; PHP unavailable |
Isolation prevented one model from inheriting another’s implementation. Within each prompting style, both models received identical prompts. Comparing styles within a model examines the prompting contrast; comparing models within a style examines the model contrast.
Both prompts included common isolation instructions. “Minimal” describes the task wording, not an unscaffolded session. These verbatim task excerpts omit surrounding instructions; line wrapping is added for readability.
Minimal excerpt:
Add a responsive live market clock to the Beast's Almanack
website for Tokyo, London, and New York.
It also required flags, AM/PM formatting, daylight-saving handling, existing-site styling, desktop/mobile support, inspection and validation.
Detailed excerpts, with omissions marked:
Create a plan before implementation.
[...]
Use JavaScript and Intl.DateTimeFormat. Use Asia/Tokyo,
Europe/London and America/New_York IANA timezone identifiers.
Do not manually calculate timezone offsets.
[...]
If anything fails, correct it and repeat validation before finishing.
The detailed prompt additionally named files to inspect, emphasized the homepage and prescribed layout, syntax and DST checks. The contrast was outcome plus constraints against outcome plus procedure. Multiple instructions changed together, so this was not a test of length alone.
Smaller patches, longer runs
These are the recorded results from the Beast’s Almanack internal benchmark, September 2026. Times include setup, agent execution and validation; they are harness wall-clock measurements, not model-only inference latency.
| Model | Prompt | Seconds | Files | Added lines | JS | Zones |
|---|---|---|---|---|---|---|
| GPT-5.5 | Minimal | 186.387 | 3 | 250 | Pass | Pass |
| GPT-5.5 | Detailed | 237.650 | 3 | 101 | Pass | Pass |
| GPT-6 Astra | Minimal | 226.689 | 9 | 252 | Pass | Pass |
| GPT-6 Astra | Detailed | 313.796 | 4 | 124 | Pass | Pass |
“Pass” means static checks passed: JavaScript syntax and zone-string detection. No hardcoded offsets were detected by the heuristic. Source inspection additionally confirmed the zones were connected to Intl formatters without manual timezone arithmetic.
All four invocations exited successfully, but overall validation remained incomplete. PHP was unavailable, and every implementation still required manual and visual review. Blank intervention fields mean unmeasured, not zero interventions.
| Minimal → detailed | GPT-5.5 | Astra |
|---|---|---|
| Added lines | 250 → 101 | 252 → 124 |
| Fewer additions | 59.6% | 50.8% |
| Extra elapsed time | 51.263 s | 87.107 s |
| Time increase | 27.5% | 38.4% |
Detailed prompts coincided with smaller patches and longer runs in both models. Logs show planning, validation and command retries. Astra detailed also attempted browser checks that failed. Some repeated checks followed genuine corrections; repetition alone does not establish waste. These events cannot be assigned precise shares of the time difference.
Instructions create work as well as constrain output. Whether that work buys useful confidence needs separate evaluation.
GPT-5.5 finished sooner under both prompt styles. One observation per condition cannot establish that it is generally faster than Astra.
What the counts conceal
GPT-5.5 minimal built a substantial homepage section with extra date/timezone labels and decorative treatment. Its detailed counterpart placed a compact widget inside the hero. Much of the reduction came from narrower presentation.
Astra minimal included an 81-line retained regression suite. Removing those lines leaves 171 non-test additions. Comparing 171 with the detailed run’s 124 gives approximately 27.5% fewer non-test additions, rather than 50.8% fewer total additions. Even that comparison contains different scope and resilience choices.
Astra’s nine-file footprint also deserves inspection:
| Artifact | GPT-5.5 minimal | Astra minimal |
|---|---|---|
| Markup | Homepage section | Reusable global template and header integration |
| JavaScript | Shared main.js | Dedicated market-clock.js |
| Styling | Homepage CSS | Shared component CSS |
| Flags | Emoji | Three SVG assets |
| Loading | Existing script | Enqueue integration |
| Retained tests | None | 81-line regression suite |
The additional files served modularity, artwork and validation. Global placement nevertheless affected more pages and required broader review. The minimal prompt said “website,” leaving that scope ambiguous.
The Astra suite executed the actual runtime with a mocked DOM and clock. It covered winter/summer offsets, DST transitions, noon/midnight formatting, timer lifecycle, restoration and unsupported zones. Passing executions were logged. This run left the strongest inspectable regression-test artifact among the four, without establishing overall model superiority or browser correctness.
Each implementation made tradeoffs. GPT-5.5 minimal favored richer presentation. GPT-5.5 detailed produced the smallest patch but rebuilt formatters each tick and scheduled a timer even without clock elements. Astra minimal added lifecycle handling and reusable tests. Astra detailed used a compact homepage component, cached formatters and conditional script loading, while retaining no test file.
Files and lines are descriptive metrics, not quality scores.
Both minimal prompts found Intl
Neither minimal task prescribed Intl.DateTimeFormat. Both models independently selected it with Asia/Tokyo, Europe/London and America/New_York.
Named zones let the runtime apply timezone rules instead of requiring application-maintained offset arithmetic. The API also supports 12-hour formatting. MDN documents these options.
The explicit recipe was unnecessary to elicit that architecture in these two observations. This was not uniquely an Astra finding: GPT-5.5 made the same choice. Correct API selection still needs implementation testing.
My practical inference is to distinguish requirements from hints. Specify an API when compatibility or architecture requires it. When it merely states the solution you expect the agent to infer, test whether that instruction contributes anything.
Give the agent a prompt contract
My working interpretation is that prompting can move toward specification design: useful context, clear constraints and evidence of completion, with engineering judgment inside those limits.
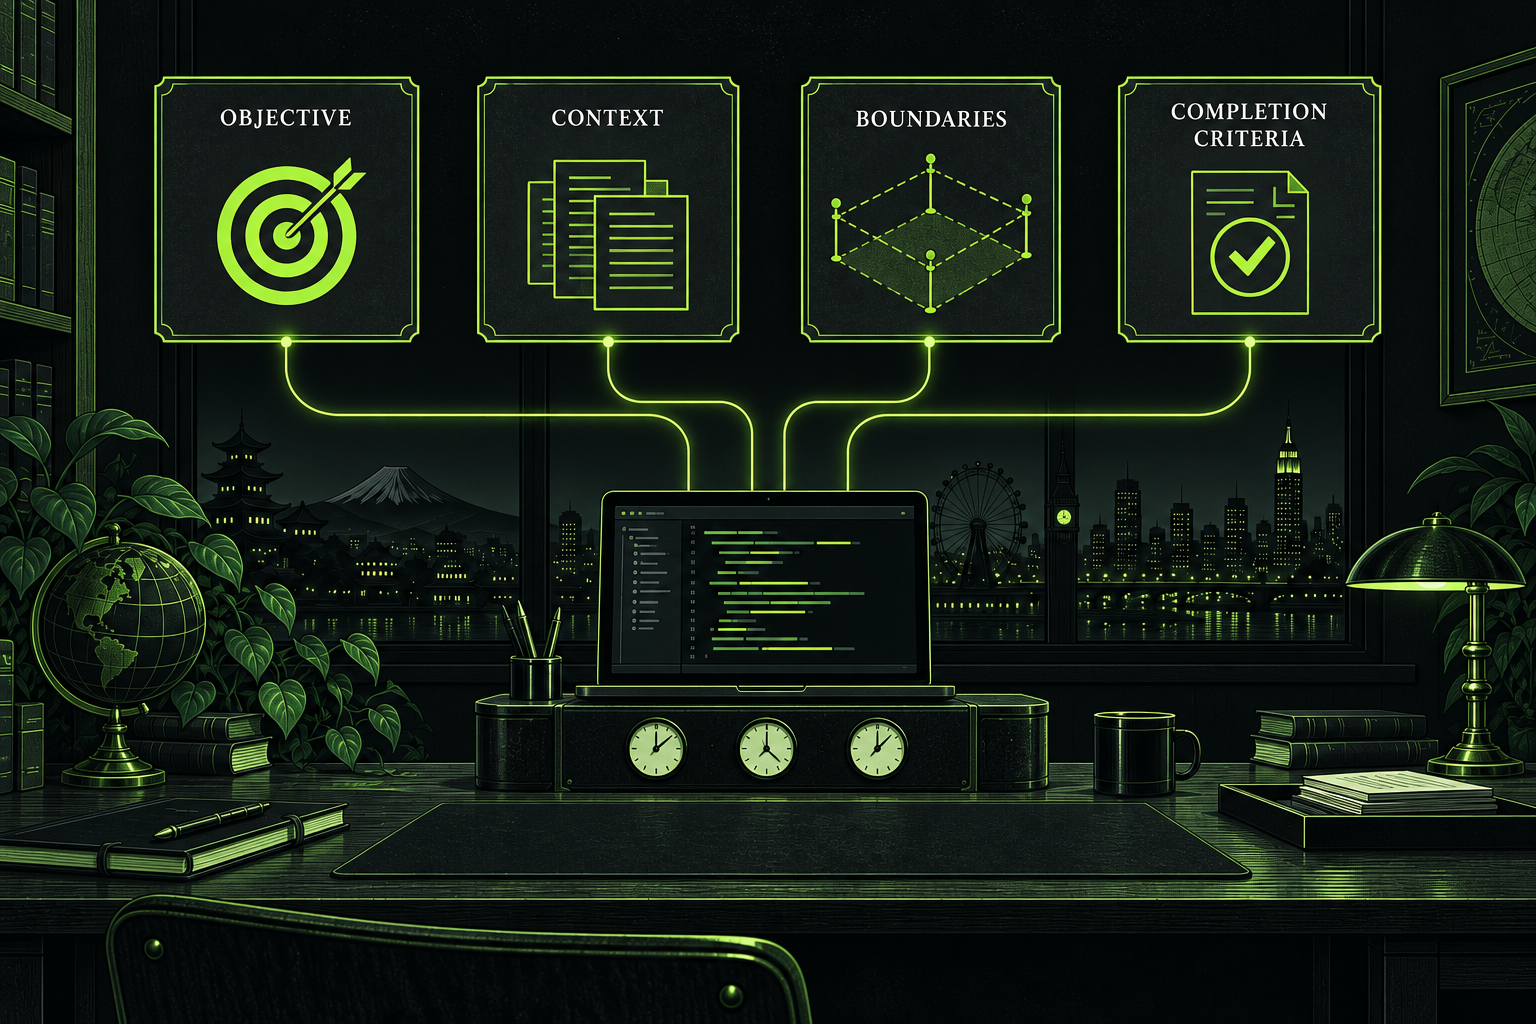
| Element | What it supplies |
|---|---|
| Objective | The result the user needs |
| Context | Project facts relevant to decisions |
| Boundaries | Constraints and authorization limits |
| Completion criteria | Required checks, evidence and handoff |
Instead of prescribing a reading order and every implementation step, I would try this new illustrative prompt, not a benchmark input:
Objective:
Add live Tokyo, London and New York clocks to the homepage,
with flags and 12-hour AM/PM time.

Context:
Use the existing WordPress theme's design and integration
conventions. Inspect relevant files. Keep the display compact.

Boundaries:
Handle DST without hardcoded offsets. Preserve unrelated
behavior. Work locally; do not change production data,
commit, push or deploy.

Completion:
Validate actual timezone behavior, updates and responsive
layout with appropriate available checks. Fix affected
failures and recheck. Report changed files and evidence.
If a required runtime is unavailable, identify what remains
unverified and leave the implementation ready for review.
This is not necessarily the shortest request. Homepage placement earns explicit words because the experiment exposed that ambiguity. A missing browser remains a validation gap rather than becoming a green result.
For developers, this focuses review on consequential choices. For quantitative researchers, it puts evaluation criteria ahead of attractive numbers. For technical recruiters, an inspectable artifact and an honest explanation offer better discussion material than a patch-size score.
Detailed instructions still matter when procedures are requirements: migrations, legacy integration, destructive operations, compliance or safety-sensitive work. Keep strict architectural boundaries and reproducible checks. Keep reminders supported by recurring observed failures. Every instruction should earn its place.
What this experiment cannot establish
There was one task, one repository and one observation per condition, without randomized order or repetitions. There were no confidence intervals or statistical significance tests.
The detailed prompt bundled several changes, and the resulting deliverables differed. Agent validation varied in depth and persistence. PHP and controlled browser evaluation were missing; inherited CLI configuration was incompletely captured. Static checks cannot establish accessibility, visual quality or regression-free behavior.
These results cannot rank overall correctness, cost, token efficiency or general model speed. They describe four inspectable implementations.
A proposed next round would use three tasks across two models and two prompt styles, with multiple repetitions, randomized order, common acceptance criteria and working PHP/browser evaluation. Bug fixes, refactors and features would come first; data-pipeline and C++ tasks could follow. Individual instructions could then be varied separately.
OpenAI’s recommendation sent me back to the instruction stack. These runs gave me a reason to examine it: both minimal prompts found the appropriate timezone architecture, both detailed prompts produced smaller patches and longer runs, and a minimal run left the strongest retained test artifact.
The useful question is what each instruction still contributes. The next prompting skill may be knowing which instructions the model no longer needs, and being able to show why.
References
- Eric Provencher, OpenAI Developers, Rethinking skills and prompts for GPT-6 Astra, September 11, 2026.
- Beast’s Almanack internal benchmark, September 2026. Four preserved runs dated September 13; measurements and implementation observations come from the read-only analysis snapshot. The evidence archive is internal.
- MDN Web Docs, Intl.DateTimeFormat() constructor. External references verified September 13, 2026.